011 min
The problem the bias-variance tradeoff describes
A team trains a model to predict how many minutes a food delivery will take. It uses distance, time of day and weather. The first model is a straight line through the data. It is wrong in the same way every time. It predicts 25 minutes for every long trip in the rain, and rain trips actually take longer, and the line cannot bend to follow that.
So the team switches to a very flexible model. This one fits every past delivery almost exactly. When it meets a new week of deliveries, its predictions are scattered. One odd trip in the training data, a courier who got lost, has changed the model's answer for similar trips.
These are two different failures. The straight line makes a systematic error: the same mistake in the same direction, whichever sample of deliveries it learns from. The flexible model makes an unstable error: its predictions change a lot from one training sample to another. Machine learning practitioners call the first bias and the second variance.
The problem is that the fix for one failure causes the other. Adding flexibility removes the systematic error and adds the unstable error. Removing flexibility does the reverse. That is the bias-variance tradeoff. It tells you why a model cannot simply be made as flexible as possible.
022 min
How the bias-variance tradeoff works
To make the two terms precise, imagine repeating the whole model-building process many times. Each time you collect a new training sample from the same source and train a new model. Each model then makes a prediction for the same input, such as one particular delivery.
- Bias is how far the average of those predictions is from the correct value.
- Variance is how much those predictions differ from each other.
- Irreducible error is the part of the outcome that no model can predict, because the outcome itself has randomness in it. In statistics this randomness is called noise.
We use a running example from here on: a model that predicts delivery time from distance. Use one input, so every model is a curve on a plot of distance against minutes.
The decomposition
For squared prediction error, the total error at one input splits into three parts that add up exactly:
Expected error = Bias squared + Variance + Irreducible error
Squared error means each miss is squared before averaging, so a miss of 4 minutes counts sixteen times as much as a miss of 1 minute. The split above holds for that measure of error. Other error measures have decompositions that differ in form, and the three-part sum is specific to squared error.
The irreducible term is a lower limit on total error. In Fortmann-Roe's words, that third term is the noise term in the true relationship that cannot fundamentally be reduced by any model. Two couriers on the same route at the same time still differ by a few minutes for reasons the data does not record. No amount of modelling removes that difference.
Why the two move in opposite directions
Model complexity means how many different shapes a model can take. A straight line has two adjustable numbers, so it can take few shapes. A curve with fifteen adjustable numbers can take many.
A model with few shapes cannot follow the real pattern if the pattern is curved. That produces bias. A model with many shapes can follow the real pattern, so its bias is low. But it can also follow the random differences in whichever sample it was given. Those differences change from sample to sample, so its predictions change too. That produces variance.
Neal and colleagues, in a 2018 paper, summarise the classical expectation as follows: as model complexity increases, bias falls and variance increases, leading to a U-shaped test error curve. Test error is the error measured on data the model was not trained on. It is high for a very simple model because of bias, high for a very complex model because of variance, and lowest somewhere between.
031 min
Bias and variance as offset and scatter
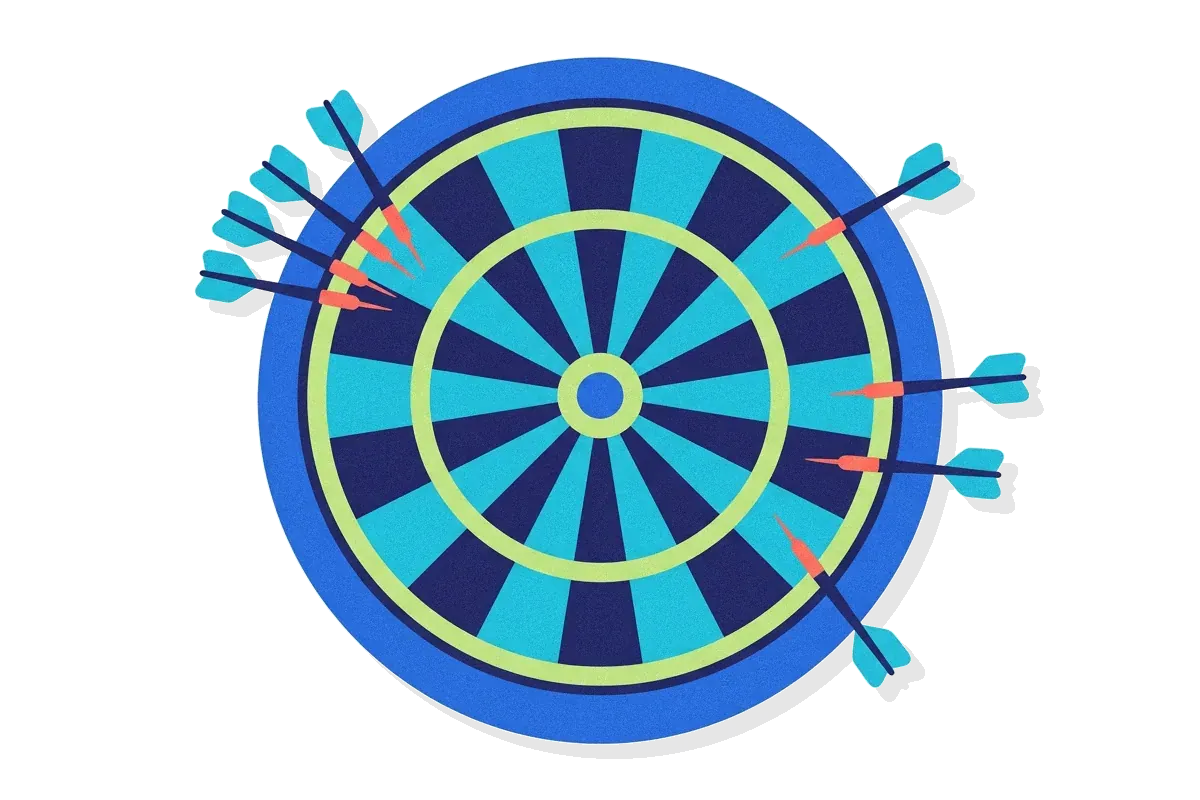
A target diagram makes the difference visible. Fortmann-Roe describes it this way: the centre of the target is a model that predicts the correct value perfectly, and each hit on the target is one model trained on one random training sample. Hits far from the centre are bad predictions.
Two separate things can be wrong with a cluster of hits:
- The cluster can be off-centre. All the hits land to one side of the target. That is high bias. Taking more hits does not fix it.
- The cluster can be spread out. The hits land all over the target, even if their average is the centre. That is high variance. Averaging many hits would fix it, but in practice you get one hit, not the average.
The second point matters. A common first instinct is that bias is the worse problem, because a biased model is "fundamentally wrong", while a high-variance model is at least right on average. Fortmann-Roe argues this reasoning fails. In practice modelers are always dealing with a single realization of the data set, so the long-run average is not what you ship. What you ship is one model trained on the data you actually have, and for that model bias and variance matter equally.
042 min
A concrete example: polynomial degree
The scikit-learn documentation includes a small experiment that shows the whole tradeoff in one chart. It is a checkable example, and you can run it yourself.
The data comes from a known function: part of a cosine curve, cos(1.5 * pi * x). The example draws 30 sample points from it and adds a small random amount (standard deviation 0.1) to each one, so the samples do not lie exactly on the curve. It then fits polynomial models of degree 1, 4 and 15 to the 30 points. Degree means the highest power of x the model may use: degree 1 is a straight line, degree 15 is a very wavy curve.
The documentation describes the three results in plain terms:
- Degree 1, a straight line. In the documentation's words, a linear function is not sufficient to fit the training samples. It misses the curve in the same way whichever 30 points it sees. That is underfitting, and it is bias.
- Degree 4. The documentation says this approximates the true function almost perfectly. Four powers give it enough shapes to follow a cosine over this range.
- Degree 15. For higher degrees the model overfits the training data, that is, it learns the noise of the training data. Fifteen adjustable shapes are more than 30 noisy points can pin down, so the curve bends to pass through each point. A new set of 30 points would produce a different wavy curve. That is variance.
The example measures this with cross-validation: it trains on part of the data and measures the mean squared error on the part held out, repeated over 10 splits. The held-out error is high for degree 1, low for degree 4 and high again for degree 15. That is the U-shaped curve from the earlier figure, with three points on it.
052 min
A second case: choosing k in k-nearest neighbors
The first example changes complexity through a polynomial degree. A second case changes it through a different dial, in a different kind of model. The variable that differs is the model type: here the model is k-nearest neighbors, which predicts a new case by averaging the k most similar cases in the training data. Fortmann-Roe uses it in the same essay.
His task is to predict a voter's party registration from two measures, wealth and religiousness. Both measures are simulated, and the data are labelled as hypothetical in the essay. A random fraction of registrations was changed on purpose to add noise.
Here k is the dial.
- With a k of 1, the separation between Democrats and Republicans is very jagged. Each prediction copies one training voter, including that voter's unusual label. The boundary also has small regions of one party inside the area of the other. Those regions change when new training data is drawn. That is variance.
- At a k near 20, the boundary is smooth and follows the true dividing line well.
- At a k near 80, the two parties blur together. The boundary is very smooth and does not change much between samples, but it no longer matches the true line. That is bias.
For this model the tradeoff has an exact form. Fortmann-Roe derives that the variance term falls as 1/k times the irreducible error, so a larger k always lowers variance. The bias term grows as farther neighbors are averaged in.
What the two cases teach together: the tradeoff does not depend on one algorithm. In polynomials, complexity is the degree. In neighbors, complexity runs the opposite way, because a smaller k gives a more flexible model. A reader who learns "bigger number means more complex" from the first case would get the second one backwards. The rule is about flexibility, not about the size of any one setting.
062 min
What the bias-variance tradeoff means for your work
The tradeoff turns into a concrete decision whenever someone chooses a model, a feature set or an amount of training time. The most useful tool it gives you is a diagnosis: is the model failing because of bias or because of variance? The two failures need opposite fixes.
The check is to compare the error on the training data with the error on data the model has not seen. Keep a separate test set that is never used during training, and a validation set (or use cross-validation) for choosing between models.
| Training error | Error on unseen data | Likely cause | Direction of the fix |
|---|---|---|---|
| High | High, close to training error | High bias (underfitting) | More flexible model, better features |
| Low | Much higher than training error | High variance (overfitting) | More data, simpler model, averaging |
| Low | Low, close to training error | Neither is a large problem | Stop tuning |
| High | Much higher still | Both, or a data problem | Check the data and the labels first |
Different roles meet this in different places.
- An engineer choosing a model decides how flexible it may be. A decision tree with no depth limit has low bias and high variance. Limiting its depth raises bias and lowers variance. The decision is where to set that limit, and the answer comes from held-out error, not from the training score.
- A PM scoping a data collection effort decides whether more data will help. More training data lowers variance. It does not lower bias. If the diagnosis says high bias, a bigger training data budget will not improve the product, and the team should change the model or its inputs instead.
- A founder judging a vendor's accuracy claim can ask which data the number was measured on. A score on the training data says nothing about variance. A score on a test set the vendor never tuned against is the figure that predicts how the model behaves for customers.
072 min
How to move along the tradeoff
Each lever below changes bias, variance or both. None of them works for free.
| Lever | Effect on bias | Effect on variance | Cost |
|---|---|---|---|
| More flexible model (more parameters, deeper trees, smaller k) | Lowers | Raises | More risk of overfitting |
| Simpler model or stronger regularization | Raises | Lowers | More risk of underfitting |
| More training samples | Little change | Lowers | Data collection and labelling |
| Better input features | Can lower | Can raise | Engineering time |
| Averaging many models (bagging) | Little change | Lowers | More compute at training and prediction time |
Regularization means adding a penalty or a limit that keeps the model from using its full flexibility, for example a cap on tree depth or a penalty on large weights. It trades a little extra bias for a larger drop in variance.
Bagging is short for bootstrap aggregating. It builds many copies of the training data by random selection with replacement, trains one model on each, and averages their predictions. Fortmann-Roe notes that bagging and other resampling techniques can be used to reduce the variance in model predictions. Random forests use this idea. In his words, in Random Forests the bias of the full model is equivalent to the bias of a single decision tree, which itself has high variance. Averaging many trees lowers the variance and leaves the bias where it was.
081 min
What the bias-variance tradeoff does not solve
It does not reduce irreducible error. If two customers with identical recorded features behave differently, no model separates them. Tuning for bias and variance can only reach that limit. Teams that keep tuning after held-out error stops improving are usually at the limit already.
It does not cover data that differs from the training data. The tradeoff describes error on new samples from the same source. If the world changes after training, for example the delivery routes change, the model's error grows for a reason that is neither bias nor variance as defined here. This is a separate problem, and a validation set drawn from old data will not show it.
It is not a rule that complex models always fail. A common overclaim is that a model with more parameters than training samples must overfit badly. The next section covers evidence that this does not always hold for neural networks. The tradeoff is a statement about an average over training samples, and it describes squared error cleanly. It is not a guarantee about every model family.
It does not tell you the right complexity. It tells you that one exists and why. Finding it requires measuring on held-out data, which is why generalization is tested directly and not predicted from theory.
092 min
Where the evidence is contested
The classical U-shaped picture is a textbook result for models such as polynomials and nearest neighbors. For very large neural networks, recent work disagrees with it.
Belkin, Hsu, Ma and Mandal posted a paper in December 2018 (published in PNAS in 2019). Their abstract says that very rich models such as neural networks are trained to exactly fit the data, which means they interpolate it. They add that classically, such models would be considered over-fit, and yet they often obtain high accuracy on test data. They proposed a double descent curve: test error follows the classical U shape up to the point where the model can just fit the training data exactly, then falls again as the model grows larger.
Nakkiran and colleagues, in a December 2019 paper, reported double descent in a variety of modern deep learning tasks, and found that it also occurs as the number of training epochs grows. An epoch is one full pass through the training data. They also found regimes where increasing the number of training samples actually hurts test performance. This contradicts the simple rule from the earlier section that more data only lowers variance.
Neal and colleagues, in October 2018, measured bias and variance directly in neural networks. They found that both bias and variance can decrease as the number of parameters grows. They note that the claim of a tradeoff in neural networks goes back to Geman et al. (1992), and they call the evidence used to support it shaky.
The objection is stated fairly as follows. The tradeoff is a mathematical identity for squared error, so it is not wrong. What is contested is the claim that variance must rise as a model gets larger, because the measurements above show that it can fall.
Where this leaves a practitioner: the diagnosis in this article, comparing training error with held-out error, still works, because it measures the outcome directly. What is unsafe is a rule such as "this network has more parameters than samples, so it will overfit". Test it on held-out data instead. For small tabular models, the classical picture remains a good guide.
101 min
The bias-variance tradeoff vs. nearby concepts
The nearest neighbours are overfitting and underfitting. They are symptoms. The tradeoff is the reason behind them. The deciding fact is that overfitting and underfitting describe what you observe in one trained model, while bias and variance describe how the error behaves across many possible training samples.
| Term | What it describes | How you detect it |
|---|---|---|
| Bias | Systematic error, the same in each training sample | Training error is high |
| Variance | Error that changes between training samples | Held-out error is much higher than training error |
| Underfitting | A model too simple for the pattern | Usually the result of high bias |
| Overfitting | A model that has learned noise in the sample | Usually the result of high variance |
| Irreducible error | Randomness in the outcome | Remains after all other tuning |
Two more distinctions help. Statistical bias in this article means error in the average prediction. It is not the same as social bias in data, such as a dataset that under-represents a group, which is a data-quality problem and has its own causes and fixes. And the bias term in a neural network, the constant added to each unit's output, is an ordinary adjustable number and has nothing to do with the bias in this tradeoff.
?8 questions
Questions people ask
What is the bias-variance tradeoff in simple terms?
Is high bias the same as underfitting?
Is high variance the same as overfitting?
Will more training data fix high bias?
How do I tell whether I have a bias problem or a variance problem?
Does the tradeoff apply to deep neural networks?
What is irreducible error?
How does bagging relate to the tradeoff?
§5 sources
Sources
Show all 5 sourcesHide sources
Fortmann-Roe, S. (2012). Understanding the Bias-Variance Tradeoff.
scikit-learn developers. Underfitting vs. Overfitting (documentation example).
Belkin, M., Hsu, D., Ma, S., Mandal, S. (2018). Reconciling modern machine learning practice and the bias-variance trade-off. arXiv:1812.11118.
Nakkiran, P., Kaplun, G., Bansal, Y., Yang, T., and others (2019). Deep Double Descent: Where Bigger Models and More Data Hurt. arXiv:1912.02292.
Neal, B., Mittal, S., Baratin, A., Tantia, V., and others (2018). A Modern Take on the Bias-Variance Tradeoff in Neural Networks. arXiv:1810.08591.